I spent this week at eTail Boston, and if you looked at the agenda, you’d …
Cloud-native POS platform for seamless omnichannel customer experience.
A single hub for all promotions campaigns.

A comprehensive solution designed to simplify and give you ownership of the inventory lifecycle.

A native post-transaction reconciliation module built into Jumpmind Commerce.

The most advanced synchronization solution for databases and file systems.
Data configuration and batch automation across different disparate systems and vendors.
I spent this week at eTail Boston, and if you looked at the agenda, you’d …
Consumers are expected to spend more than $146 billion on back-to-school shopping this year, and …
Shoptalk Europe wrapped up in Barcelona last week and I want to get a few …
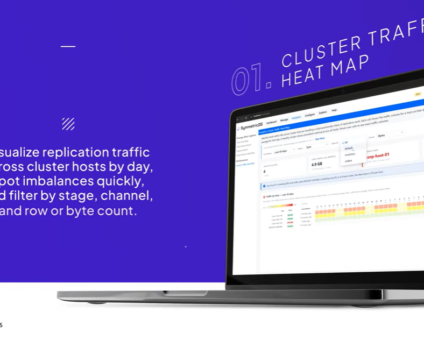
We built 3.18 because the question we kept hearing from customers changed. It used to …
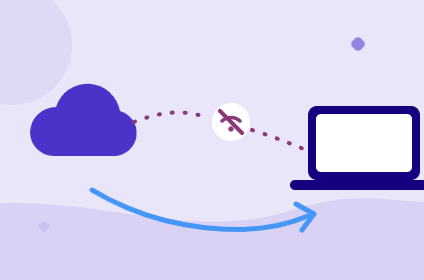
Quick answer: Edge AI agents running on technician laptops, warehouse devices, or hospital workstations need …
Everyone is talking about what AI will do for their business. Very few people are …
Introduction In retail, POS updates have traditionally been quarterly events at best. From October through …
Jumpmind Powers Point of Sale and Promotions Execution for Landmark Retail, One of the Largest …
Retail Technology Leader Jumpmind to Enable Mobile Point of Sale and Inventory Management for DTLR/VILLA …
We built 3.18 because the question we kept hearing from customers changed. It used to …
The offering gives security teams a practical path to risk management and accountable AI COLUMBUS …
The insights have implications for retail technology in the store: it must help mind information …
Cloud-native POS platform for seamless omnichannel customer experience.
A single hub for all promotions campaigns.
A comprehensive solution designed to simplify and give you ownership of the inventory lifecycle.
A native post-transaction reconciliation module built into Jumpmind Commerce.
The most advanced synchronization solution for databases and file systems.
Data configuration and batch automation across different disparate systems and vendors.
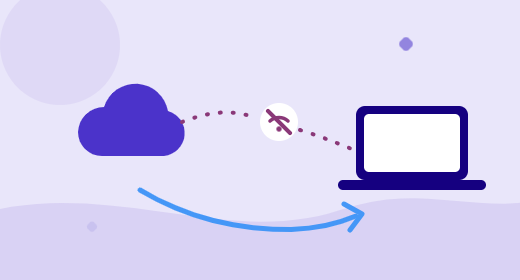
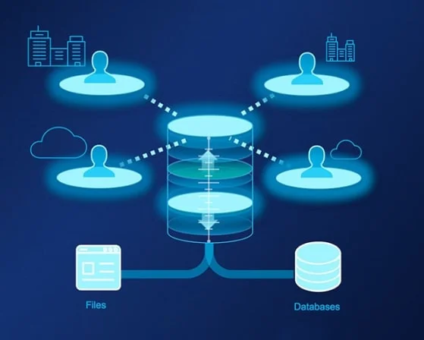
Quick answer: Edge AI agents running on technician laptops, warehouse devices, or hospital workstations need to keep functioning during network outages and automatically reconcile data once connectivity returns. This requires a data layer built for intermittent connectivity from the ground up, not one that assumes a constant connection and breaks when it doesn’t have one.
Most enterprise data infrastructure quietly assumes something that isn’t true at the edge: a stable, always-on network connection. That assumption holds fine in a data center. It falls apart the moment you deploy an AI agent onto a technician’s laptop in a rural service area, a handheld device on a warehouse floor, or a workstation inside a network-segmented hospital ward.
And edge AI is exactly where a lot of the highest-value, real-world agentic AI use cases are showing up.
Picture three common scenarios:
In each case, the agent still needs to function. It can’t throw an error and wait. And when connectivity returns, whatever happened locally during the outage needs to reconcile cleanly with the central system, without someone manually cleaning up conflicts afterward.
Most data replication architectures aren’t built for this. They assume a live connection and either fail or queue indefinitely when they don’t have one, leaving edge devices running on increasingly outdated local data with no clear path back to consistency.
A data layer that’s genuinely built for edge AI needs a few specific characteristics.
Local capture during outages. When a device loses connectivity, it should keep capturing local changes rather than simply stopping. The agent keeps working against its local database; the changes just queue up for later delivery.
Automatic resumption, not manual intervention. Once the connection is restored, queued changes should transfer automatically. Nobody should have to notice the outage happened and manually kick off a sync.
Ordered, conflict-aware reconciliation. Changes that arrived during the outage need to process in the correct order, with clear rules for resolving conflicts, rather than just overwriting whichever record happened to sync last.
Firewall-friendly connectivity. Edge environments, especially clinical and industrial ones, often restrict inbound connections for security reasons. A push/pull communication model that doesn’t require the edge device to accept inbound traffic tends to fit these environments far more easily than architectures that do.
Get this right, and the result isn’t just an agent that survives an outage. It’s an agent whose local data is always current relative to the last moment it was connected, and that fully catches up the moment it’s back online, without a human in the loop cleaning up the mess.
That’s a meaningfully different reliability bar than “the app didn’t crash.” It’s the difference between an edge AI deployment that works in a demo and one that survives contact with an actual warehouse floor, service van, or hospital network.
We break down the full architecture behind this, including how automatic recovery and conflict resolution work together at the node level, in our technical whitepaper. Read the full whitepaper, “SymmetricDS: Data Replication for the Agentic AI Era”.
What happens to an edge AI agent’s data if it loses connectivity for an extended period?
With the right architecture, the agent keeps operating against its local database and continues capturing changes locally. Nothing is lost; it simply queues for transfer once the connection returns.
Does reconnecting after an outage require manual syncing?
No, not with a properly designed edge replication layer. Transfer resumes automatically once connectivity is restored, and queued changes are processed in order according to configured conflict resolution rules.
Why can’t edge devices just accept inbound connections from the central system instead?
Many edge environments, particularly clinical and industrial ones, restrict inbound connections for security reasons. Architectures built around edge devices initiating outbound push/pull communication tend to work within those restrictions far more easily than ones requiring inbound access.